How We Designed and Developed a Secure and Scalable Service Control Component at SQL Cockpit
A blog post explaining our engineering choices for building a secure, and scalable service control across Windows, Linux and macOS Operating Systems.
SQL Cockpit Engineering | October 8, 2026 | 18 min read
In this article
When we started building SQL Cockpit Service Control, the requirement sounded straightforward: we needed a reliable way to install, configure and manage SQL Cockpit background components on customer machines.
The difficult part was making that work across different operating systems and multiple environments on the same machine. Windows Server, Linux and macOS have different service managers, filesystem conventions and credential stores. Development, Testing and Production also need separate identities, configuration and state.
We built the architecture around one shared component codebase, isolated environment instances and thin platform adapters. We separated configuration validation from installation, kept secrets outside the configuration file and made recovery part of the installation model.
This article explains the approaches we chose, the problems each one addressed and why those decisions fit together.
First, what is the SQL Cockpit Agent?
The SQL Cockpit Agent is a small background application. It does not depend on a desktop window or somebody remaining logged in. Its role is to stay available and perform work for SQL Cockpit.
- Communicating with SQL Cockpit services
- Receiving work
- Collecting information
- Sending results
- Reporting health information
- Retrying failed operations
- Handling scheduled tasks
That made the operating system’s service manager the appropriate place to manage its lifecycle. On Windows, that means Windows Services. On Linux, it means systemd. On macOS, it means launchd.
Start this application in the background, keep track of it, and allow the operating system to start, stop or restart it.
We treated that lifecycle requirement as shared behaviour. The platform-specific details belonged in the integration with each service manager, rather than throughout the Agent’s application logic.
So what is Service Control?
We built Service Control as the layer between SQL Cockpit’s configuration model and the operating system. That gave us one place to translate an environment configuration into the directories, service registrations and settings required on the machine.
The reason was practical: installing an Agent should not require users to create Windows Services manually, write systemd unit files or assemble launchd definitions.
The platform adapter handles the appropriate service manager. The user works with a SQL Cockpit environment and component, rather than an operating-system-specific installation procedure.
Install the SQL Cockpit Agent for my Production environment.That separation gave us a consistent installation model while keeping the actual operating-system operations explicit inside Service Control.
Why we chose one Agent with multiple instances
One of our first decisions was whether Dev, Test and Production needed separate Agent applications. We considered the obvious arrangement:
- SQLCockpitAgentDev
- SQLCockpitAgentTest
- SQLCockpitAgentProd
Those applications would all authenticate, communicate with SQL Cockpit, process work, write logs, report health and retry failures. Maintaining separate implementations would duplicate the same behaviour without solving the isolation problem.
We therefore made Dev, Test and Production instances of the same Agent. The executable is shared; each instance receives its own configuration and identity.
This put the boundary in the right place. Environment membership comes from the instance’s configuration, rather than from a separately maintained executable.
Creating Agent instances dynamically with Service Control
We used the Service Control app to create environment-specific Agent instances from the shared installation. For each environment, Service Control reads its configuration, validates the requested instance and registers a separate background service through the platform adapter.
On Windows, those instances appear in Services with environment-specific display names. The screenshot below shows SQL Cockpit Service Host (dev), SQL Cockpit Service Host (prod) and SQL Cockpit Service Host (test), all running with Automatic startup. Each service hosts an Agent instance with its own environment configuration and identity.
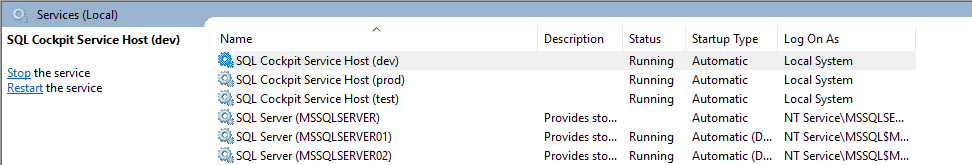
Registering each instance separately lets us start, stop or restart one environment’s Agent without stopping the others. Creating another environment adds its configuration and service registration; it does not require another Agent codebase. That is the practical benefit of dynamic instance creation: we reuse the executable while keeping each environment’s lifecycle and state separate.
Why we kept one codebase
A retry bug illustrates the maintenance cost of separate Agents. With one project per environment, the same fix needs to be applied repeatedly. Add three operating systems and that arrangement produces nine combinations to maintain:
- Windows Dev Agent
- Windows Test Agent
- Windows Production Agent
- Linux Dev Agent
- Linux Test Agent
- Linux Production Agent
- macOS Dev Agent
- macOS Test Agent
- macOS Production Agent
We separated packaging from instance configuration. Platform packages come from the shared Agent codebase:
Within an installed package, environment instances remain separate:
That means a shared-code fix is made once and delivered through the platform packages. We still account for platform-specific behaviour, but we do not maintain different Agent logic for every environment.
Cross-platform does not mean identical
We did not try to make Windows, Linux and macOS appear identical. Their conventions matter, especially for service registration, credentials and filesystem permissions.
Windows brings mechanisms such as:
- Windows Services
- Windows Credential Manager
- DPAPI
- Windows filesystem locations
- Windows-specific APIs
Linux has its own conventions:
- systemd
- Linux filesystem permissions
- /etc
- /var/lib
- /var/log
- Unix users and groups
And macOS has different equivalents:
- launchd
- Keychain
- macOS filesystem conventions
- Native Apple APIs
Our approach was to isolate these differences behind platform interfaces. That kept the shared model small and made it clear which code was responsible for respecting each operating system’s conventions.
Keeping operating-system code at the edge
We kept authentication, API communication, job processing, retries, health reporting, telemetry and configuration parsing in the shared core. Those behaviours do not need to know how a Windows Service differs from a systemd unit.
The shared code expresses an operation at the component level:
Install this component as a background service.
The platform adapter translates that operation into a Windows Service, systemd service or launchd definition. This platform abstraction gave us a clear boundary between application behaviour and operating-system integration.
The benefit was more than code reuse. It also made responsibility easier to follow: a platform registration problem belongs in the adapter; an Agent retry problem belongs in the shared core.
Defining environment boundaries with lanes
We used the term lane for an isolated SQL Cockpit environment. Development, Testing and Production are separate lanes, each with its own configuration, identity and state.
We chose a lane as the boundary because an environment is broader than an Agent process. The Agent is one component inside it:
Production
- SQL Cockpit Agent
The same model also describes a group of components. This illustrative example shows why we kept the lane boundary independent of any particular component type:
Production
- Agent
- Collector
- Worker
- Gateway
- Integration Service
The lane owns the environment boundary. Components remain reusable within that boundary. We built that distinction into the model so adding a component type does not require redefining what an environment is.
Describing the installation in JSON
We chose JSON to describe the components and environment that belong on a machine. It gave us a structured format that applications and deployment tooling can read and write, with a schema we can validate before installation.
A simplified example looks like this:
{
  "environment": "prod",
  "components": [
    {
      "type": "agent",
      "enabled": true
    }
  ]
}
The configuration expresses the intended result:
This machine should contain a Production environment with the SQL Cockpit Agent enabled.
We kept Windows Service definitions and systemd unit-file details out of that model. The configuration describes what belongs in the environment; Service Control determines how to install it on this platform.
That decision prevented platform implementation details from becoming part of every configuration file.
Why we used desired state
We adopted a desired-state model instead of asking users to supply a sequence of low-level installation commands:
- Create directory
- Copy file
- Create service
- Set account
- Start service
The environment configuration describes the end result:
Production should contain an Agent.Service Control works out the operations required to reach that state. We made that planning step explicit so changes to platform-specific installation procedures do not force changes to the user’s environment definition.
This also gave validation something concrete to check: whether the requested end state is valid and compatible with the machine, before the installer starts applying operations.
Why we separated validation from execution
A compiler was a useful analogy for the pipeline we built. It separates reading source, checking it and producing output. We applied the same separation to configuration, validation and installation planning.
Parsing JSON was only the first step. We added structural checks, security validation and conflict detection before producing the installation plan. Platform operations come after those checks:
The reason for this ordering was straightforward: malformed or conflicting configuration must be rejected before it creates directories, copies binaries or registers services. Finding a configuration error after changing the machine makes a simple input problem into a recovery problem.
Why we treated JSON as untrusted input
We treated configuration as untrusted input even when SQL Cockpit generated it. Once a file exists on a machine, an administrator, deployment script or another application can change it. It can also be damaged or replaced.
Its origin therefore did not remove the need for validation. We rejected the assumption that a file’s presence makes its contents safe:
This file exists, therefore it must be safe.
Putting the trust boundary at the configuration reader meant the same checks applied to application-generated files, hand-edited files and deployment-tool output.
Schema validation
We defined the expected structure with JSON Schema. This made required fields, recognised component types and allowed properties part of an explicit contract.
- schemaVersion must be a number
- environmentId must exist
- components must be an array
- component type must be recognised
- unknown properties are not permitted
We rejected unknown properties because silently ignoring an unrecognised field can hide a typo or a mismatch between configuration versions. A file that appears accepted may otherwise produce a different installation from the one the administrator intended.
Structural validation gave the later planning stages predictable input and brought configuration errors to the start of the process.
Why we versioned the schema
We included a schema version so Service Control can identify the configuration contract it is reading. Configuration formats evolve, and guessing a file’s meaning from whichever fields happen to be present is fragile.
For example, one format can identify itself as:
{
  "schemaVersion": 1
}
A different version identifies a different contract:
{
  "schemaVersion": 2
}
We made version checking part of validation. That gives us an explicit boundary for supported formats and for any migration between them, instead of silently interpreting an unfamiliar file as the current format.
Separating environment IDs from names
We separated the human-readable environment name from its internal identity. Renaming “Production” to “Live” or “Main Production” is a display change; it must not create a new environment or change which credentials an Agent uses.
{
  "id": "prod",
  "name": "Main Production"
}
The ID remains stable while the name changes. We used that stable identity as the basis for associating the environment with:
- Agent registrations
- Credentials
- Service names
- Storage
- Logs
- Remote SQL Cockpit records
That decision kept friendly names out of the identity boundary and made environment renames easier to reason about.
Environment isolation
We gave each lane separate configuration, logs and data locations. Sharing the Agent executable does not imply sharing its writable state.
dev/
- config/
- logs/
- data/
test/
- config/
- logs/
- data/
prod/
- config/
- logs/
- data/
We treated those directories as environment boundaries. Development writes belong in Development’s state, Test credentials belong to Test, and Production logs remain associated with Production.
The directory model made separation explicit. Combined with lane-specific credentials and service identities, it prevented a shared binary from becoming a reason to mix environment state.
Giving every service instance a unique name
Operating systems identify registered background services by name, so service identity needed the same separation as files and credentials. We based the naming model on the component and lane, rather than using one global Agent service name.
The Windows naming pattern looks like:
- SQLCockpit-Agent-Dev
- SQLCockpit-Agent-Test
- SQLCockpit-Agent-Prod
The corresponding systemd template pattern expresses the instance in the unit name:
- sqlcockpit-agent@dev.service
- sqlcockpit-agent@test.service
- sqlcockpit-agent@prod.service
We made service-name collisions a validation concern. Rejecting a duplicate identity before registration avoids overwriting or confusing an existing environment’s service.
Detecting port collisions before installation
We also checked listening endpoints as part of conflict detection. A listener binds to an address and port, such as:
127.0.0.1:5100Two components requesting the same listening address and port create a collision. In this example, Dev and Test conflict, while Production uses a separate port:
Port 5100
- Dev
- Test
Conflict: two instances request the same port.
Port 5200
- Prod
Separate port for the Production instance.
We modelled this as an endpoint conflict, rather than treating it as the machine “running out” of ports. That made the error specific enough for the administrator to resolve.
Pre-installation checks catch configuration conflicts early. The actual bind still belongs to installation verification, because availability can change between a check and the service starting.
Why we chose outbound Agent connections
Before assigning a listener to every Agent, we asked whether the Agent needed an inbound port at all. We chose an outbound HTTPS communication model: the Agent connects to SQL Cockpit and requests work.
Do you have any work for me?
That choice removed an unnecessary listener from the Agent’s deployment model and reduced the number of network settings administrators needed to manage.
- Fewer firewall rules
- Fewer network conflicts
- Simpler installation
- Reduced attack surface
- Less configuration
We kept listener configuration as a separate, component-specific concern. An automatic-allocation setting, where applicable, can be expressed without making ports part of every Agent’s identity:
{
  "port": "auto"
}
The important decision came before allocation: we established whether a component actually needed to accept inbound connections. That kept networking requirements tied to its job.
Keeping secrets out of configuration
We separated credential references from credential values. Putting an API key directly into configuration is convenient to implement, but it makes every copied configuration file another copy of the secret:
{
  "apiKey": "my-secret-api-key"
}
Configuration files travel through backups, support requests and deployment repositories. We chose to store a reference instead:
{
  "credentialReference": "sqlcockpit-prod-agent"
}
Credential resolution sits behind the platform boundary. The secure-storage mechanism depends on the operating system:
- Windows Credential Manager or DPAPI
- macOS Keychain
- Linux secret storage or protected credentials
This kept the environment configuration useful for installation and support without requiring it to carry the credential itself. It also kept platform-specific secret handling out of the shared configuration model.
Filesystem validation
We made path validation part of the security pipeline. A path is not safe merely because it is a valid JSON string. Consider:
{
  "dataPath": "../../somewhere"
}
The .. segments refer to parent directories. An installer that uses the value without resolving and validating its destination can write outside the intended installation area. This is a path traversal problem.
We resolved paths before checking them against approved SQL Cockpit locations. The check concerns the destination of an operation, rather than just how the original string is written.
Keeping that check ahead of filesystem changes made an invalid destination a configuration error, rather than an unexpected write elsewhere on the machine.
Making identity immutable after registration
We distinguished operational settings from identity. Changing a log level adjusts how an Agent behaves; changing its Tenant ID, Agent ID or Environment ID changes which registration and environment it belongs to.
We made those identity properties immutable after registration. An identity change follows an explicit lifecycle:
- Unregister Agent
- Change identity
- Issue new credentials
- Register Agent again
That choice prevented a routine configuration edit from silently repointing an existing Agent at a different tenant or environment. It also kept credentials and registration aligned with the new identity.
Least privilege
We built the service-account model around least privilege. Running every component as LocalSystem or root simplifies permission handling, but it also gives a compromised process much broader access to the machine.
Give a process only the permissions it actually needs to perform its job.
We separated the permissions required to install a service from the permissions required to run it. Installation tasks and normal Agent work have different needs; we kept that distinction in the execution model.
We also kept service identities lane-specific, so environments can use separate accounts:
- SQL Cockpit Dev Account
- SQL Cockpit Test Account
- SQL Cockpit Prod Account
This reinforced the environment boundary. Sharing an executable did not require sharing an account or granting Development access to Production’s credentials and files.
Platform validation
A structurally valid configuration is not necessarily installable on the current machine. We added platform checks before execution so compatibility errors appear before the installer modifies the environment.
A component’s supported targets can be expressed explicitly. For example:
- Windows x64
- Linux x64
- Linux ARM64
- macOS ARM64
The validation pipeline checks the machine against the component’s requirements:
- Operating system
- Architecture
- Available disk space
- Required runtime
- Permissions
- Dependencies
- Available service manager
We put these checks in planning because “valid configuration” and “valid installation on this machine” are different questions. Both need an answer before applying changes.
Checking component compatibility
We treated compatibility as a relationship between components, rather than checking only that each package was individually valid. Service Control, an Agent and another component can all be valid releases while expecting different protocols.
For example, this combination needs more than four independent version checks:
- Service Control 4.0
- Agent 3.1
- Plugin Host 2.7
- Protocol Version 5
We included compatibility requirements in component metadata. A simplified declaration looks like:
{
  "agentVersion": "4.2.0",
  "minimumServiceControlVersion": "4.0.0",
  "protocolVersion": 3
}
The version numbers here illustrate the relationship. The architectural decision was to check those requirements together before installation, so a package mismatch does not first appear as a communication failure after startup.
Transactional installation
We organised installation into validation, preparation, execution and verification, with a rollback path for failure. Installing an Agent involves several operations:
- Create directories
- Copy binaries
- Create configuration
- Store credentials
- Register service
- Start service
- Check Agent health
Successful service registration alone does not mean a successful installation. If the process cannot start or fails its health check, the machine is left in an intermediate state unless the installer has a recovery model.
We therefore made verification the point at which installation is considered successful. We also tied rollback to the changes made during installation, rather than treating cleanup as an unrelated support task.
Operating-system operations do not have all the guarantees of a database transaction. We kept that limitation explicit: rollback is a controlled recovery process, and the installer needs to account for what it changed and what can be undone.
Validate first, modify second
The central rule we applied was: do as much validation as possible before changing the machine. We put schema, identity, security, platform and compatibility checks ahead of the installation plan and its execution.
This ordering gave failures a clearer meaning. An invalid configuration is rejected before application; a failure while applying a valid plan belongs to verification and recovery.
We also made conflict reporting specific. The useful error identifies the component, environment and conflicting resource:
Installation rejected.

Production Agent requested port 5100,
but the Development Agent is already using port 5100.
That gives the administrator an actionable configuration problem instead of an unexplained partial installation.
The architecture we built
The resulting architecture separated configuration, validation, planning and platform execution. Lanes provided the environment boundary across the whole process:
Two decisions did most of the structural work. Platform abstraction isolated operating-system differences. Environment isolation separated instances, credentials and writable state.
We kept those decisions independent. Windows versus Linux is a platform concern; Development versus Production is an environment concern. Combining them into separate applications would have multiplied implementations and made isolation harder to follow.
Why we built more than an installer
The result was a deployment and orchestration layer built around components and lanes. The Agent was the starting point, but the configuration model did not make “environment” synonymous with “Agent process”.
Roles such as collectors, workers, gateways and integration services illustrate why that distinction mattered. The model has a place for a component’s requirements, identity and lifecycle without needing a new environment model for each role.
We chose the extension points deliberately: JSON describes desired state, validation checks it, planning determines the operations, and platform adapters apply them inside isolated lanes. That is how we kept component growth from becoming another collection of one-off installers.
What shaped the final design
Our starting point was the behaviour shared across platforms and environments. The Agent’s purpose stayed the same; the operating-system integration and instance configuration changed around it.
The choices we made followed from that distinction:
- One shared component codebase, with platform-specific packaging
- Multiple isolated environment instances
- Thin operating-system adapters
- Configuration that describes desired state
- Validation and conflict detection before installation
- Credential references separated from secret values
- Least-privilege service execution
- Explicit identity and compatibility checks
- Installation verification and a rollback path
Together, these choices gave Service Control a consistent deployment model. The installation request remains about the environment:
I want an Agent in my Production lane.
Service Control owns the translation into service-manager operations, secure credential handling and environment-specific state. That was the reason we built the component this way: to put deployment complexity in a predictable layer, while keeping the user’s configuration focused on the result they need.